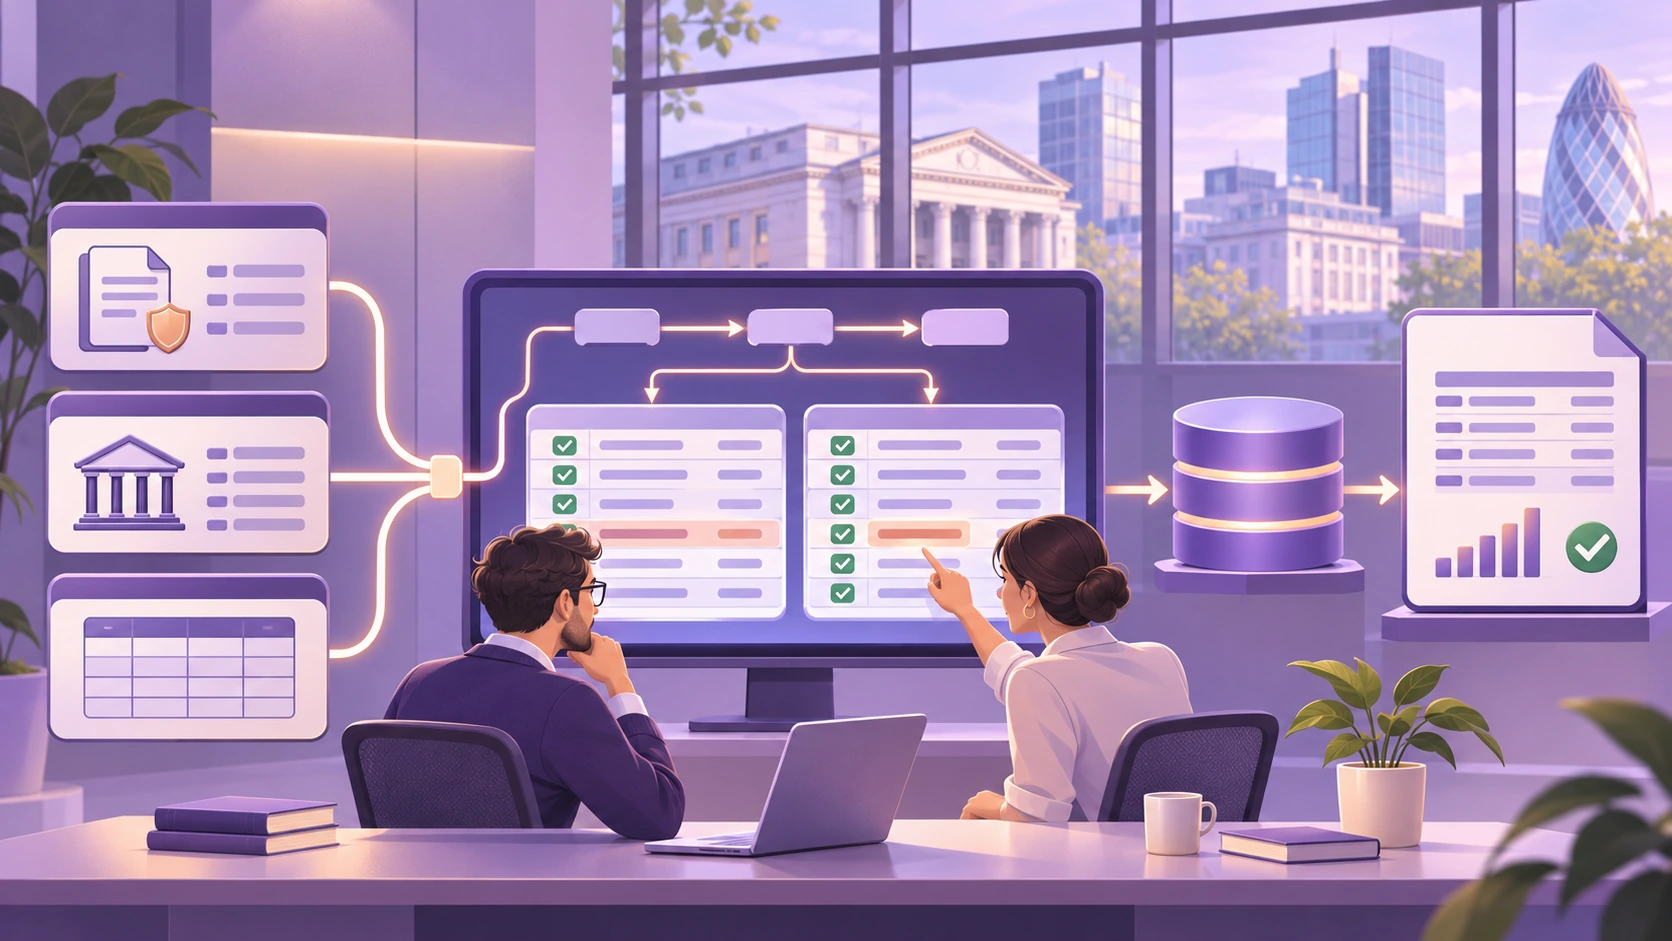
An ETL developer or data engineer in an insurer or bank moves policy, claims, transaction and ledger data into the systems that produce reserves, capital figures and regulatory reports. Hire for reconciliation, lineage and control discipline first and tools second, and in most regulated firms hire data engineers before data scientists.
What does an ETL or data engineer actually do in an insurer or bank?
They build and run the pipelines whose output ends up in signed accounts, actuarial valuations and supervisory returns. The tools look the same as at a technology company. The consequences do not.
At a product company, a late event stream means a gap on a dashboard and a rerun tomorrow. At an insurer, a late claims extract can hold up the reserving close, and the chief actuary will want to know why. At a bank, a broken feed from core banking can leave a liquidity or credit risk report wrong on the one day a supervisor asks for it.
The sources are different too. Policy administration, claims, core banking and general ledger systems often predate the people maintaining them, deliver batch files rather than clean APIs, and each define “customer”, “policy” or “account” slightly differently. Most of the job is making those definitions reconcile, every month, in a way an auditor can follow.
Why do regulators care about data pipelines?
Because the numbers a regulator relies on are only as good as the pipelines that produce them. In January 2013 the Basel Committee on Banking Supervision published its Principles for effective risk data aggregation and risk reporting, known as BCBS 239. Its title says it plainly: supervisors expect banks to aggregate risk data accurately and report it reliably, and that is data engineering work before it is anything else.
Insurance has its own version of the same pressure. According to the IFRS Foundation, IFRS 17 took effect for annual periods beginning on or after 1 January 2023. For most insurers it pulled actuarial, finance and policy data closer together than ever, and turned “where did this number come from” into an audit question rather than a curiosity.
Privacy adds a third layer. India’s Press Information Bureau announced that the Digital Personal Data Protection Rules were notified on 14 November 2025, with a phased compliance period of 18 months. Whatever your privacy counsel concludes the Rules require, data engineers will be the ones implementing it: masking, access controls, retention and deletion jobs, and logs that prove each one ran.
Should we hire data engineers or data scientists first?
In most insurers and banks, hire data engineers first. A data scientist hired onto unreconciled data spends the first year doing data engineering badly, without the authority to fix the sources, and then leaves.
The exception is a firm that already has a trusted, well governed data platform and a clear first use case, such as claims triage or lapse prediction. There, a data scientist can produce value quickly, and one strong engineer can support them. If you are unsure which situation you are in, ask the head of finance how many manual adjustments go into the month end close. A long answer means you need engineers.
The general difference between data engineering and data science is well rehearsed. The regulated finance version is shorter: engineers make the numbers trustworthy, scientists make them useful, and the order matters.
Reconciliation, lineage, handling late or restated data, and surviving schema change matter more than any single tool. SQL and Python are table stakes. What separates a strong candidate is whether they think like someone who will be asked to defend a number.
Skill | How to test it |
Reconciliation | Give two extracts that disagree by a small amount; ask them to find and explain the break |
Lineage | Pick one figure on a sample report and ask them to trace it back to source, naming every transformation |
Late and restated data | Ask how their pipeline handles a claims file that arrives after close and is corrected a week later |
Schema change | A source system renames a column overnight; ask what breaks, what alerts, and who they tell |
Point in time history | Ask them to rebuild the portfolio as it stood at last quarter end, excluding later corrections |
Explaining a break | Ask for a three sentence explanation of a reconciliation break for a chief actuary |
A few of these overlap with standard data engineering interview questions, but the scoring should change. In a regulated firm, an elegant pipeline with no reconciliation step is a fail, not a pass with notes.
Watch the brief as closely as the candidate. When a request for cloud and data engineering recruitment lists twelve tools and says nothing about the business domain, it will attract people who match keywords and miss people who have spent years closing books at an insurer. Name two or three tools that are genuinely required. Describe the data and the close cycle for the rest.
How does an analyst move into data engineering in financial services?
Start by owning a pipeline end to end, however small. Analysts in banks and insurers already know the data and the business questions, which is the harder half. What they usually lack is engineering habit: version control, automated tests, scheduled jobs, and code other people can maintain.
The practical route is internal. Take on the reconciliation or data quality work nobody wants, write it as tested code instead of a spreadsheet macro, and ask to shadow the team that runs the month end loads. Deepen SQL well past reporting queries into performance, window functions and data modelling.
The route looks much the same whether the analyst sits in Mumbai, London or one of the data and AI teams in Philippine banks and insurers. For employers, analytics recruitment and data engineering hiring work better as one conversation, because your next data engineer may already be sitting in your reporting team.
A search is a problem statement, not a vacancy, and data engineering briefs in insurance and banking usually go wrong on criteria. I see requests that insist on an exact cloud stack and ignore the one thing that is hard to teach, which is the discipline of making numbers reconcile under deadline. Before sourcing, I want to know how large the real pool is once you drop the tool list, whether the working model rules people out, and how the role is positioned. An engineer who owns the data behind the solvency or liquidity numbers has a serious job. If the brief does not say so, the right people will not stop to read it.
Frequently asked questions(FAQs)
If you are building a data engineering team for a bank or insurer and want a specialist view on the brief before you go to market, Start a conversation.